About Me
I am Qirui Liu (刘骐瑞), a master’s student at the College of Computer Science and Technology, Zhejiang University (2026–Present), fortunate to be advised by Dr. Zhixuan Chu. Previously, I studied Computer Science and Technology at Northeastern University (2022–2026), advised by Changming Xu.
My research focuses on safety alignment of large reasoning models, efficient on-policy self-distillation, and reinforcement learning for language agents. I am interested in how models can learn from their own experience to reason, interact, and align more effectively.
I was a Research Intern at TruthLab (2025–2026), working on reasoning-model safety alignment, and previously a Research Intern at Wukong Lab, Northeastern University (2023–2025), working on deep reinforcement learning and computer games.
Find my work on Google Scholar and GitHub.
🔥 News
- 2026: 🚀 We released Saferl-DeepSeek-R1-671B, a safety-aligned DeepSeek-R1-671B model, as part of our SAVeR² results, demonstrating safety alignment at the 671B scale.
- 2026: 🎉 Our work SAVeR² was accepted by NeurIPS 2026 (Poster)!
📝 Publications
Peer-reviewed research * Equal contribution
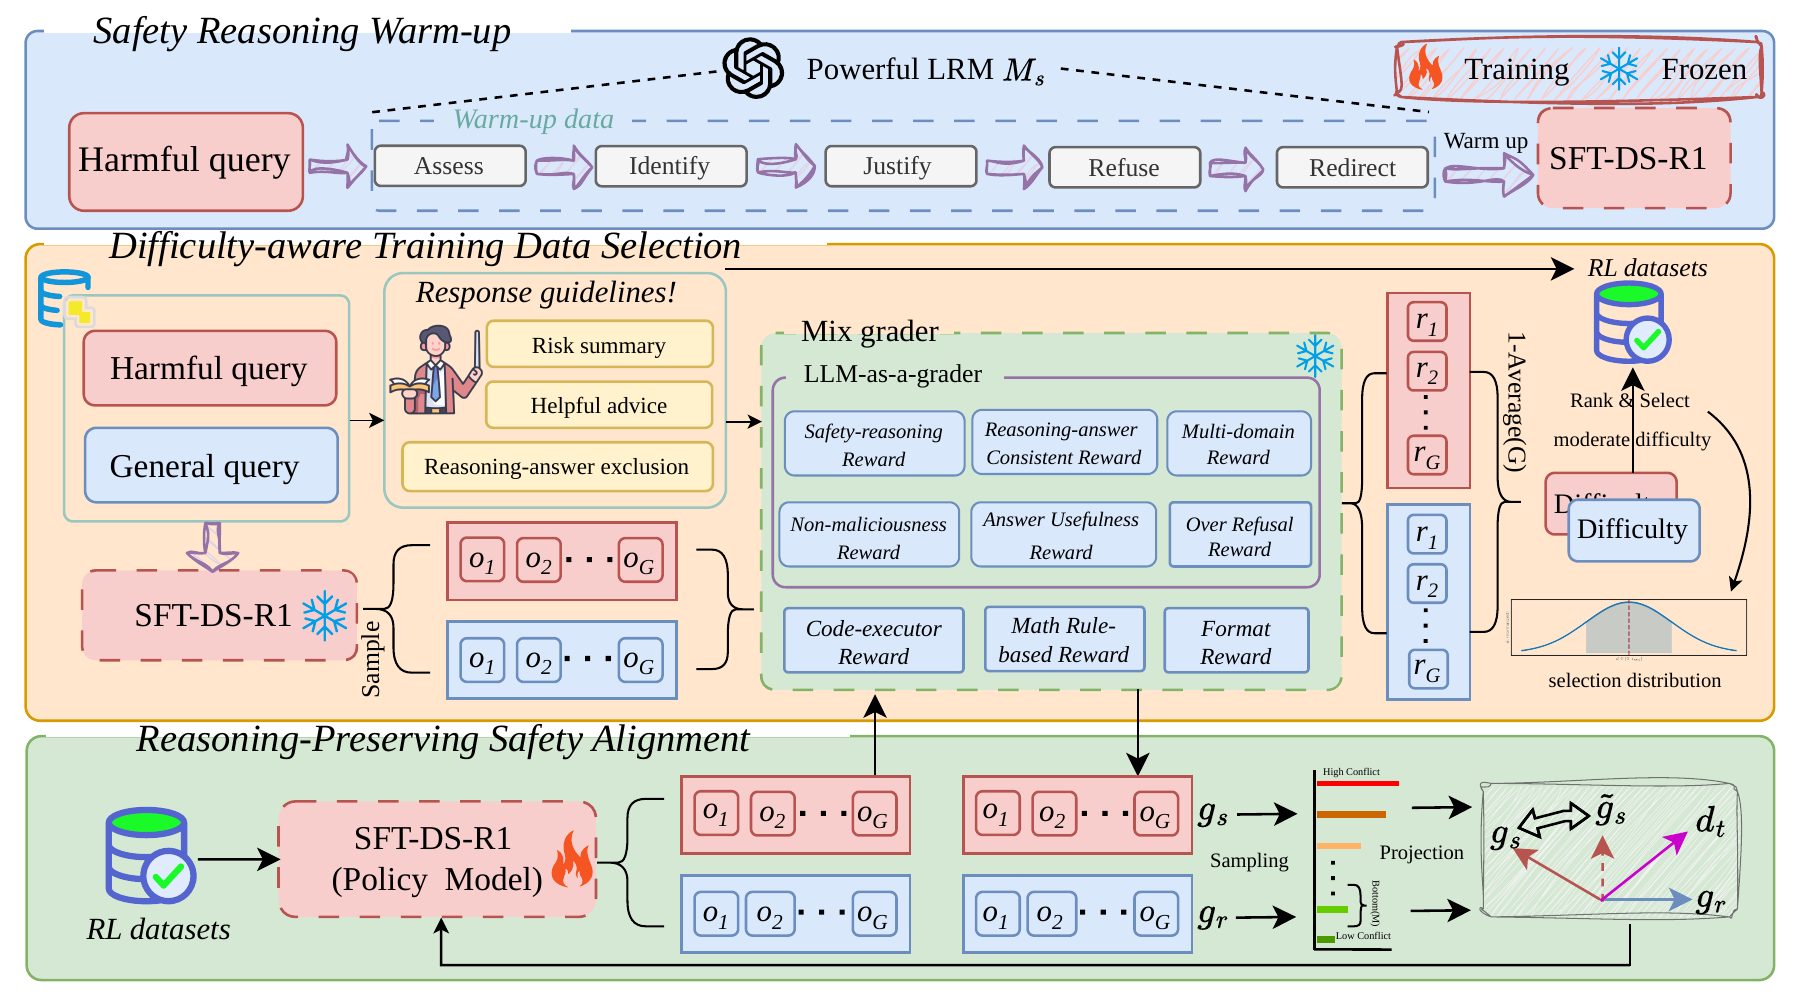
Yichen Sun*, Qirui Liu*, Yan Wang, Jianan Lin, Linbo Jiang, Shiyu Wang, Zhibo Wang, Zhixuan Chu
- Combines verifiable safety rewards, difficulty-aware data selection and reasoning-preserving gradient projection for safer reasoning models, including safety alignment of DeepSeek-R1 at the 671B scale. We release the safety-aligned 671B model as part of the paper’s results.
Preprints · 2026 * Equal contribution
Qirui Liu, Yichen Sun, Yan Wang, Yu Mi, Wei Cao, Yue Shen, Zhixuan Chu, Kui Ren
- Efficient on-policy safety distillation: halves rollout compute and updates only about 2% of tokens while preserving reasoning.
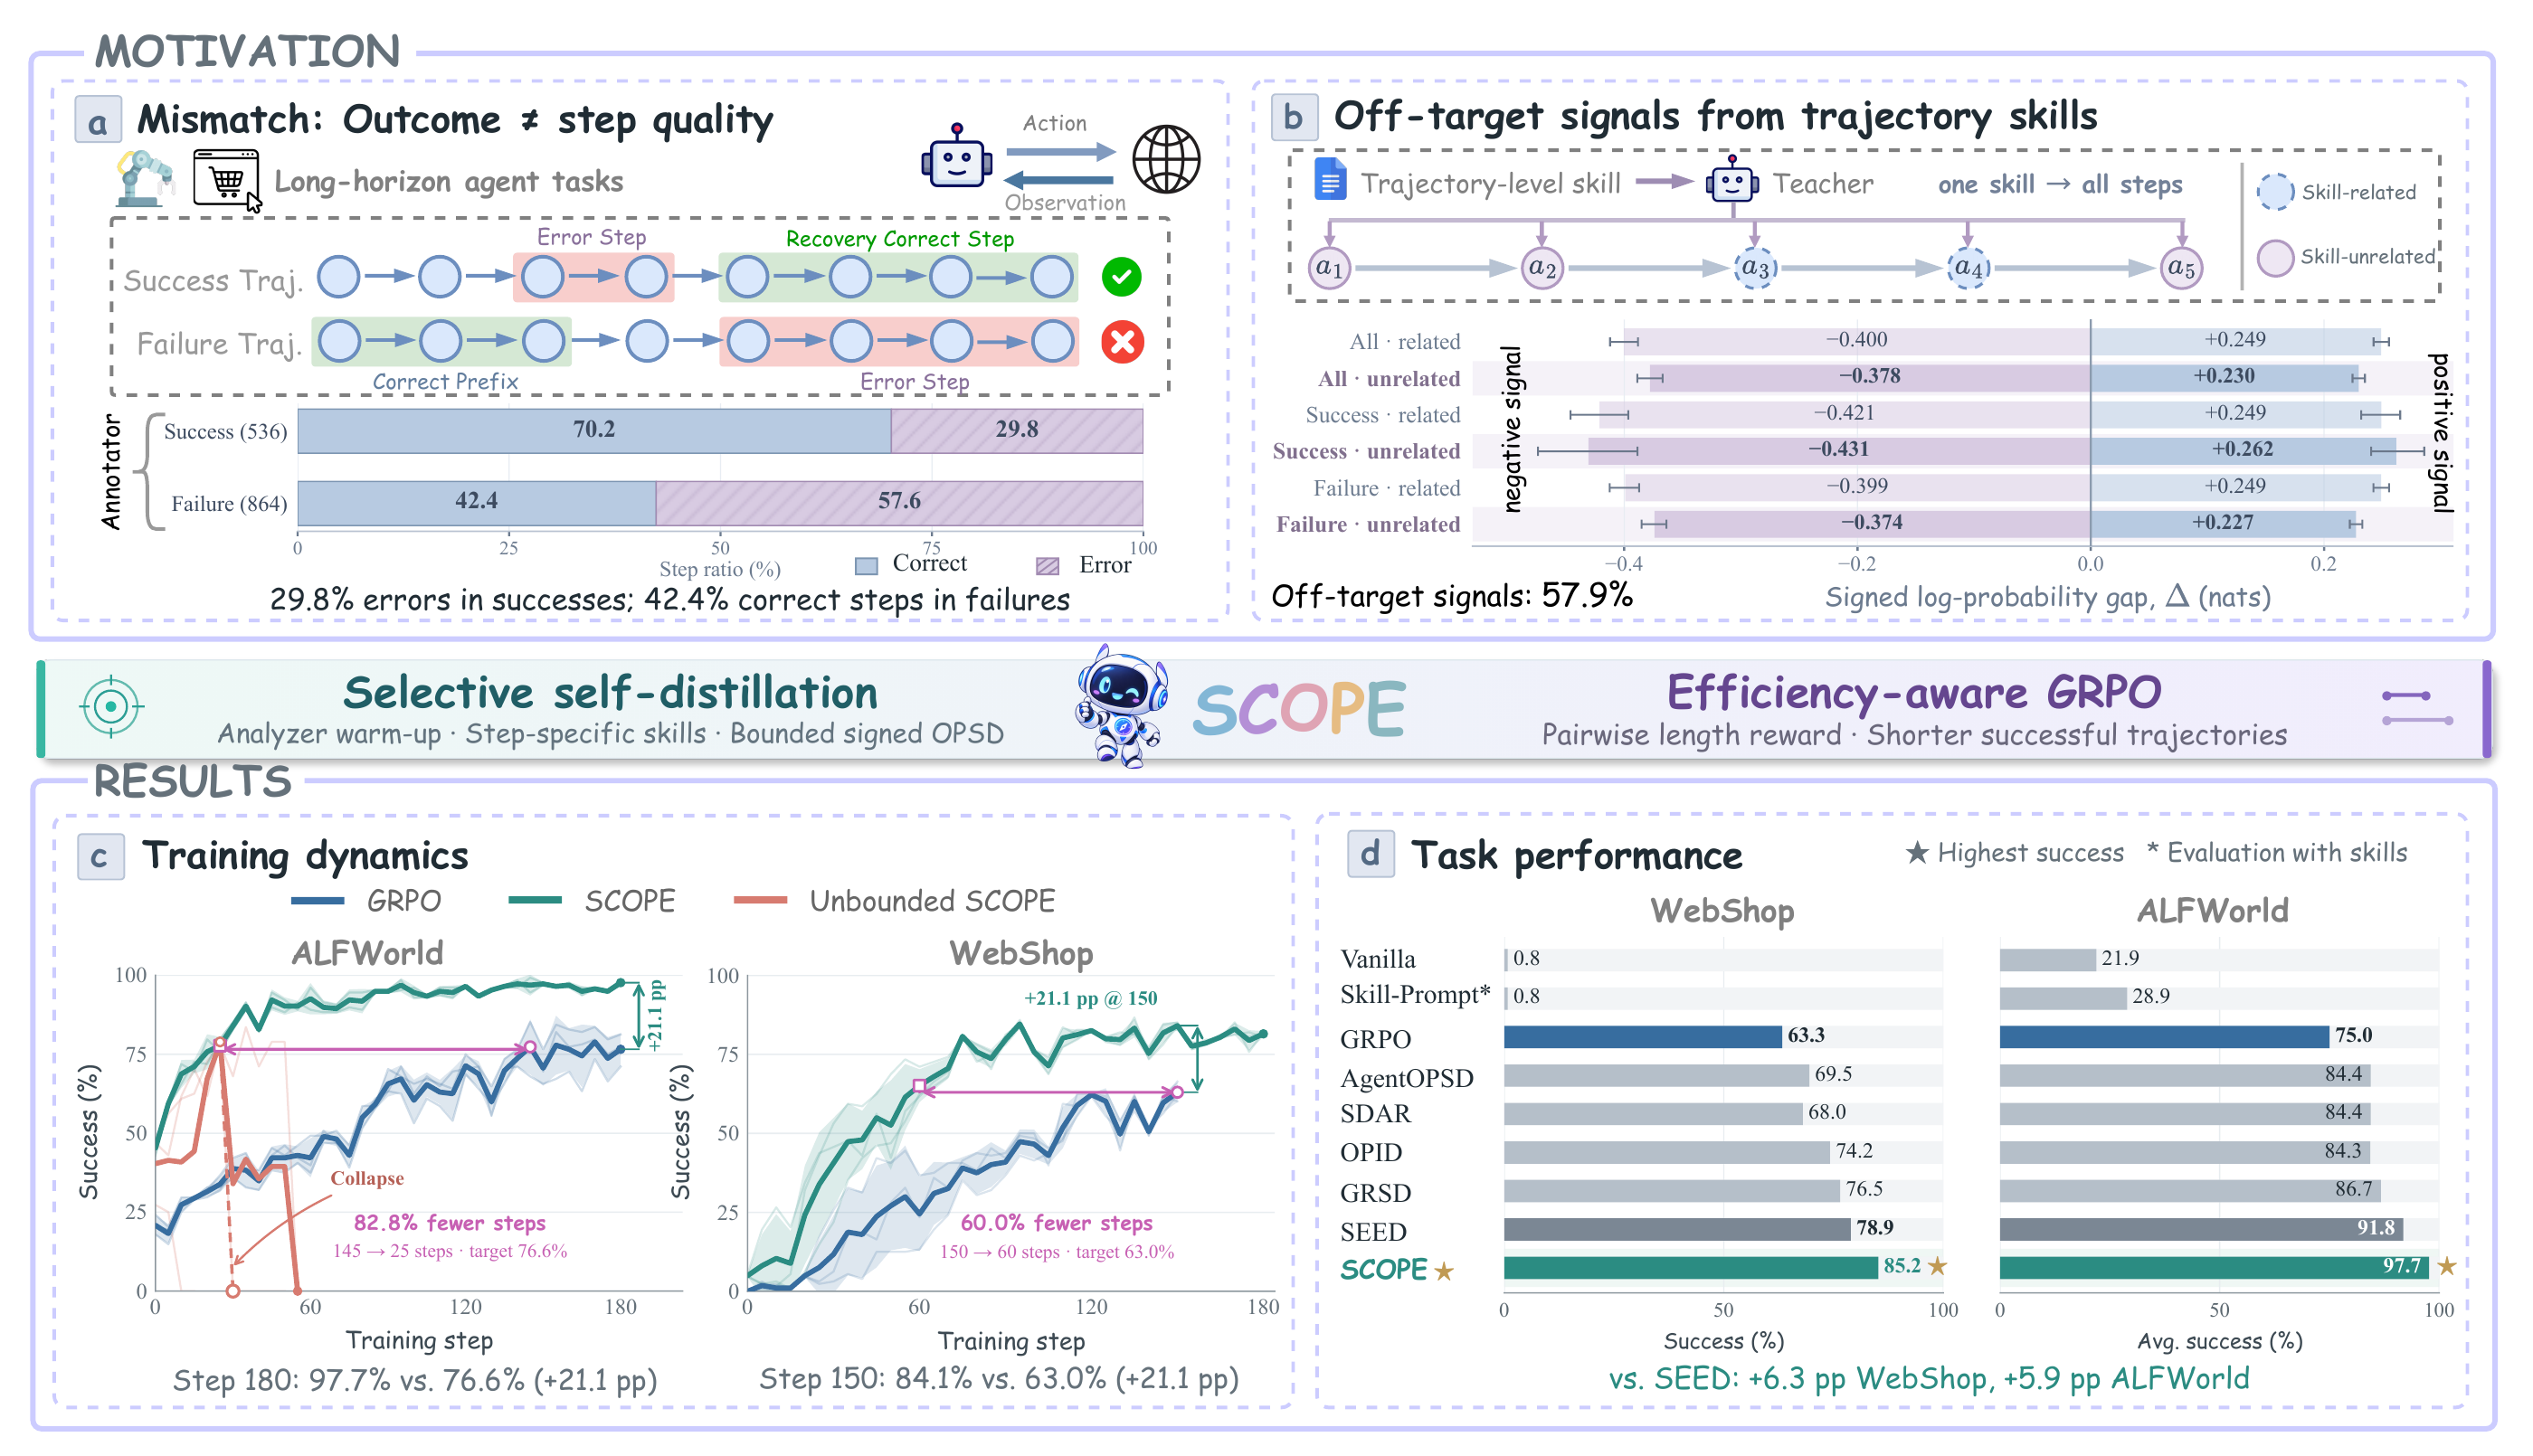
Qirui Liu*, Wei Cao*, Yu Mi, Yichen Sun, Xuekun Zhang, Lei Liu, Yue Shen, Zhixuan Chu
- Learns from self-generated, step-specific corrective skills to improve agent success and interaction efficiency.
Qirui Liu, Yichen Sun, Yan Wang, Zhixuan Chu, Linbo Jiang, Jianan Lin, Kui Ren
- Decouples formatting and lexical shortcuts to improve safety robustness while reducing over-refusal.
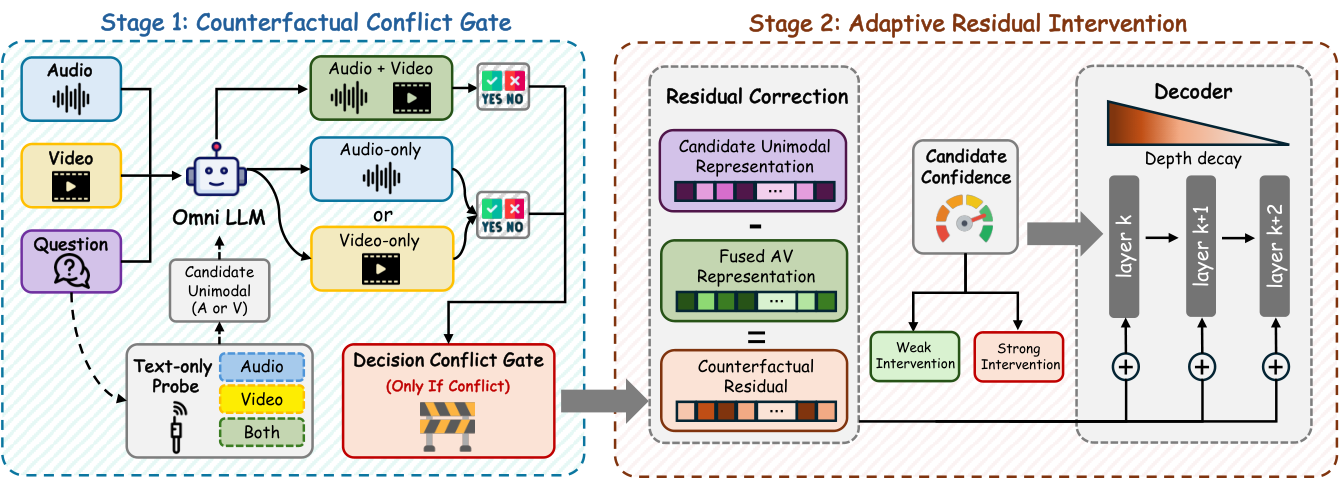
Yu Mi, Licheng Pan, Jiayi Zhu, Qirui Liu, Yitong Qiao, Changtong Xu, Tao Wei, Fei Sun, Zhixuan Chu, Kui Ren
- A training-free method that detects modality misrouting and applies confidence-adaptive residual intervention to reduce cross-modal hallucinations.
📖 Education
Master’s Student · College of Computer Science and Technology
Undergraduate Studies · Computer Science and Technology
💻 Research Internships
TruthLab
2025–2026Research Intern · Zhejiang University & Ant Group
Safety alignment and efficient distillation of large reasoning models
Wukong Lab · Northeastern University
2023–2025Research Intern
Deep reinforcement learning and computer games